An LLM router where providers bid for every prompt, giving you the lowest price that meets your requirements.
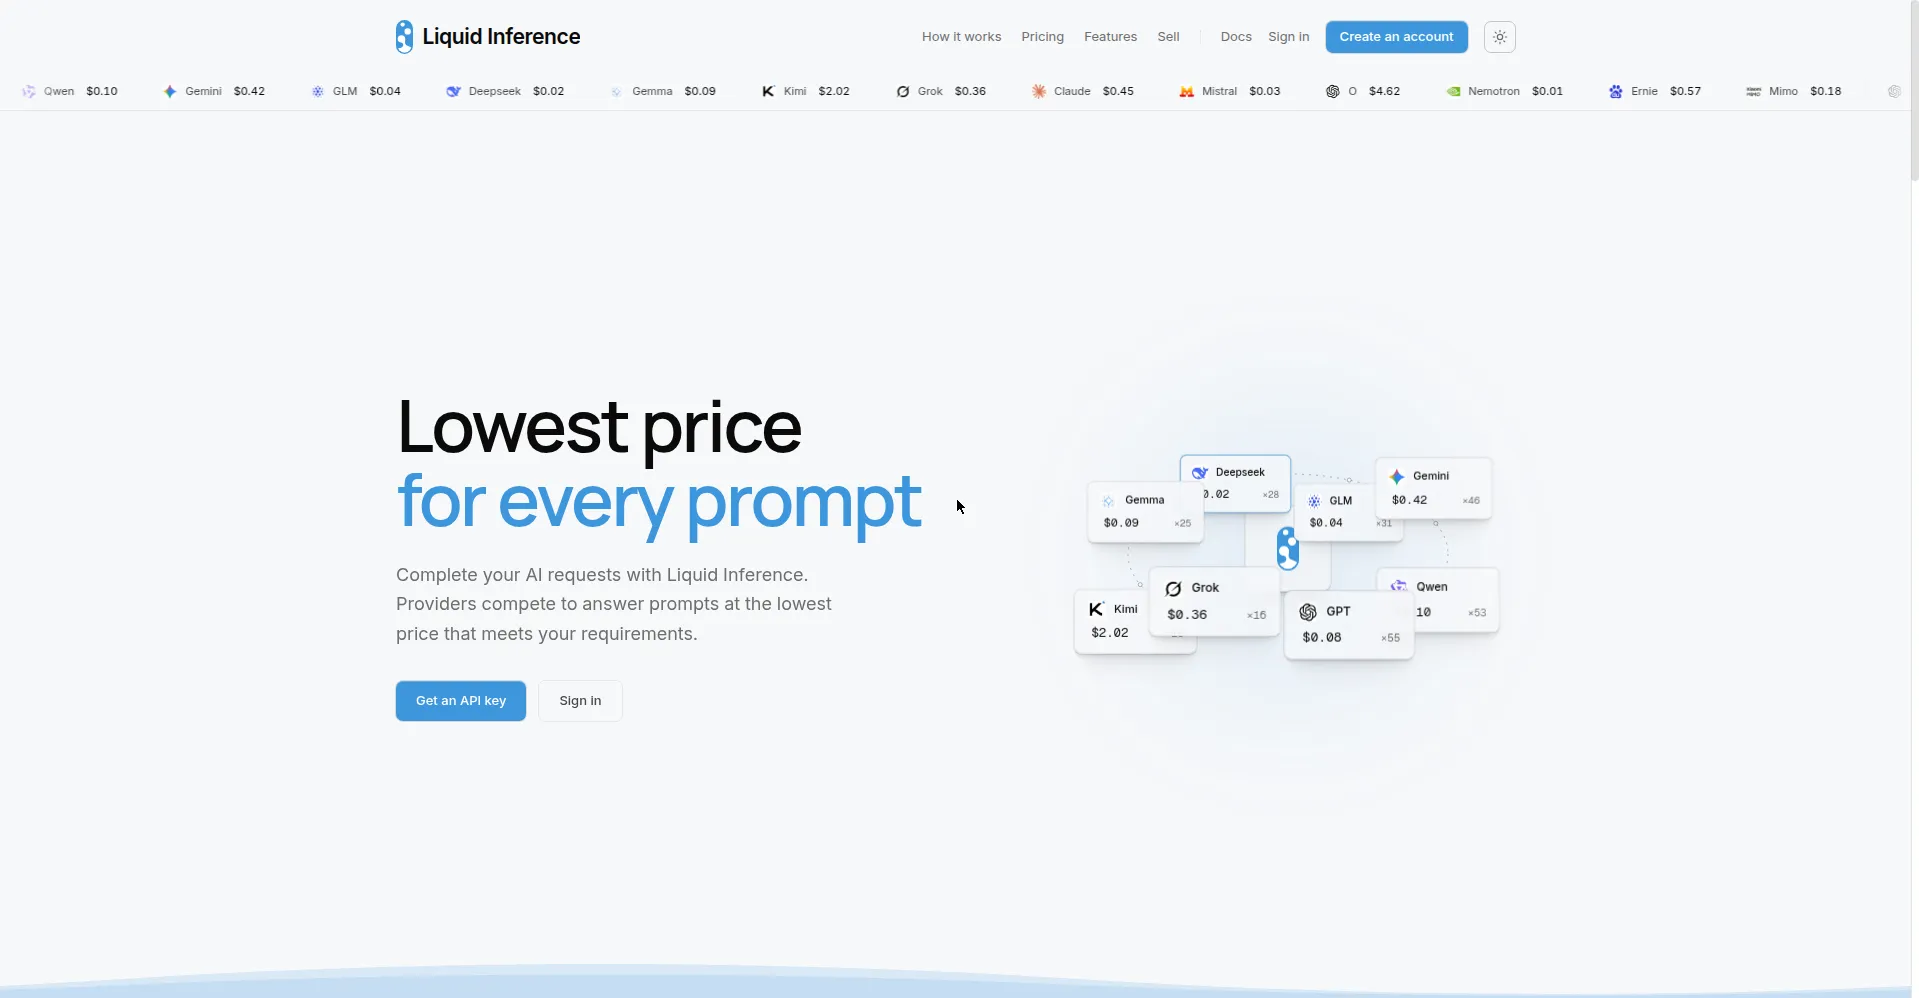
Liquid Inference homepage
1 / 2Overview
What is Liquid Inference?
LLM router where providers compete for every prompt
Liquid Inference is an LLM router where providers compete for every prompt: send your request, and providers bid to answer it at the lowest price that meets your requirements. Prices change with supply and demand, so you always get the cheapest qualifying provider.
One API key covers OpenAI Chat Completions and Anthropic Messages on a single base URL, so existing code works unchanged. Set routing rules for model, region, speed and minimum quality, put a price limit on every request, and pay only for the tokens produced. Hundreds of open- and closed-weight models are supported, including GPT, Claude, Gemini, DeepSeek, Qwen, Kimi and Grok.
Pricing is per token with output tokens priced separately — for example around $0.08 per million output tokens for GPT OSS 20B. An interactive calculator on the site shows what your workload would cost right now.
Platforms and languages
Liquid Inference Availability
Platforms
Languages
Capabilities
Liquid Inference Key Features
Provider bidding
Providers compete to answer every prompt; you pay the lowest price that meets your requirements.
One key, two APIs
OpenAI Chat Completions and Anthropic Messages on one base URL; existing code works unchanged.
Routing you control
Choose model, region, speed and minimum quality; only qualifying providers compete.
Price limit on every request
You know the most a request can cost before the model starts; pay only for the tokens produced.
Independent benchmarks
Every provider is tested regularly with standard benchmarks and the results are published.
Best for
Who uses Liquid Inference?
Developers and teams building on LLMs
Cut inference costs by routing every prompt to the cheapest qualifying provider
Plans and access
Liquid Inference Pricing
Paid
Per-token pricing; providers bid - e.g. $0.08/M output tokens for GPT OSS 20B
Common questions
Liquid Inference FAQs
How does pricing work?
Per token, with output tokens priced separately. Providers bid for every prompt, so prices move with supply and demand.
Do I need to change my code?
No. One API key works for OpenAI Chat Completions and Anthropic Messages on a single base URL.
Can I control which models serve my requests?
Yes. Choose the model, region, speed and minimum quality, and only providers that meet them compete for your prompt.
Reviews
See what the community thinks and share your experience.
—
Based on 0 ratings
Rating distribution
Community reviews
No reviews
No written reviews yet.