Web tool that tests embedding models, chunking, hybrid search and rerankers on your own documents to explain RAG failures.
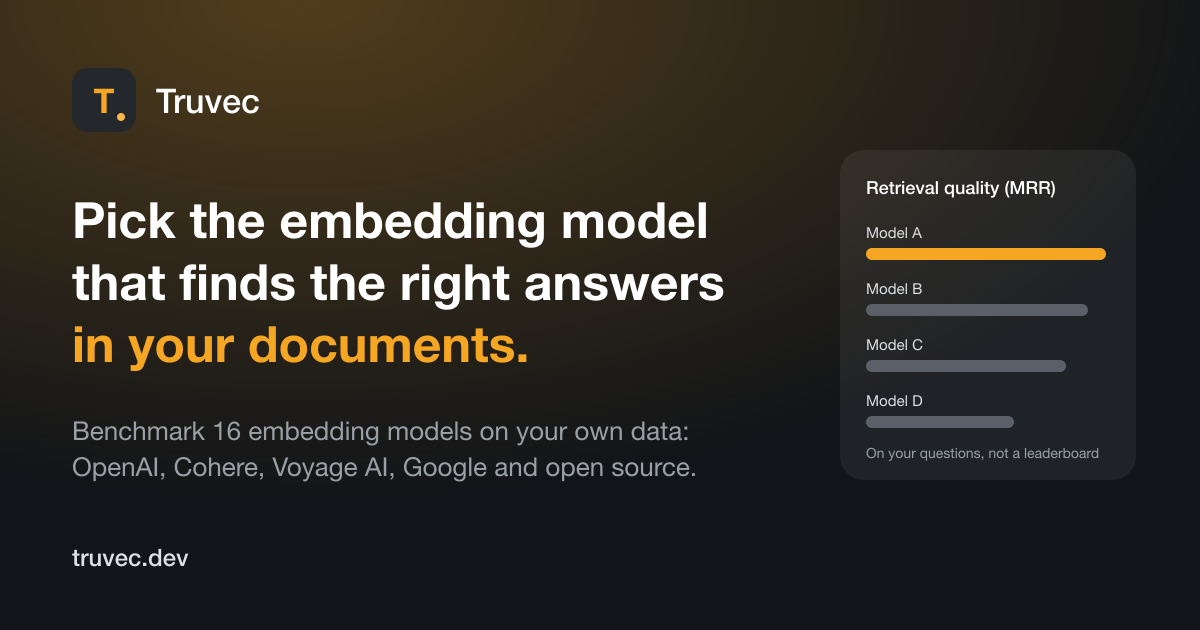
Truvec homepage: retrieval evaluation for RAG
1 / 3Overview
What is Truvec?
Find out why your RAG retrieves the wrong answers
Truvec measures RAG retrieval on your own documents, so teams stop guessing whether a change helps or hurts. Upload a sample of the corpus, generate a golden set of questions linked to the chunks that answer them, then run embedding models, chunking options, hybrid search and rerankers on the same questions.
The leaderboard ranks configurations by MRR and recall, next to latency and cost per 1,000 queries. A strategy comparison shows each change against the baseline: the questions it fixed, the ones it broke, and what it adds to query cost. The inspector puts each question next to what every configuration retrieved, and a playground lets you query any model with your own wording.
Truvec covers 16 embedding models from OpenAI, Cohere, Voyage AI, Google and open-source families, with Cohere and Voyage rerankers. A first leaderboard takes about 15 minutes, and the free plan needs no card and no provider API keys.
Platforms and languages
Truvec Availability
Platforms
Languages
Capabilities
Truvec Key Features
Compare on your own documents
Test embedding models side by side on questions about your own corpus, instead of relying on public benchmarks.
Debug failing questions
The inspector shows exactly what each configuration retrieved, including where the expected chunk ranked, so you see why it was missed.
Experiment in a few clicks
Add a reranker, change chunking, swap the embedding model or turn on BM25 hybrid search, then see what each change fixes or breaks.
Quality, speed and cost metrics
The leaderboard ranks by MRR and recall, next to latency and cost per 1,000 queries, reranking included.
No provider API keys
Embedding, reranking and question-generation usage is included, so there are no vendor keys or separate API bills.
Exportable decision report
Export a PDF with the recommendation, leaderboard, charts, costs and the full configuration so a run can be reproduced.
Best for
Who uses Truvec?
Developers building RAG assistants
Choose the embedding model, chunking and reranker on their own documents before building the pipeline
Teams migrating embedding models
Measure exactly which questions a cheaper or newer model gains or loses before re-indexing production
Plans and access
Truvec Pricing
Freemium
Free plan with no card required; Starter $129 one-time and Team Pro $349/month
Common questions
Truvec FAQs
What problem does Truvec solve?
When a RAG assistant answers from the wrong passage, nothing points at retrieval. Truvec measures retrieval on your own documents so you can see which setup finds the right answers.
Do I need my own provider API keys?
No. Embedding, reranking and question-generation usage is included, and Truvec runs the models on its own provider accounts.
How long does a first evaluation take?
A first leaderboard takes about 15 minutes for a typical sample, most of it spent reviewing the generated questions.
What can I compare?
Embedding models, chunking strategies, BM25 hybrid search and rerankers, all on the same questions and top k, with quality, latency and cost shown side by side.
Reviews
See what the community thinks and share your experience.
—
Based on 0 ratings
Rating distribution
Community reviews
No reviews
No written reviews yet.