vLLM
High-throughput, memory-efficient inference and serving for large language models.
Open-source (Apache 2.0) engine for serving LLMs — PagedAttention, continuous batching, OpenAI-compatible API on your own GPUs. Free.
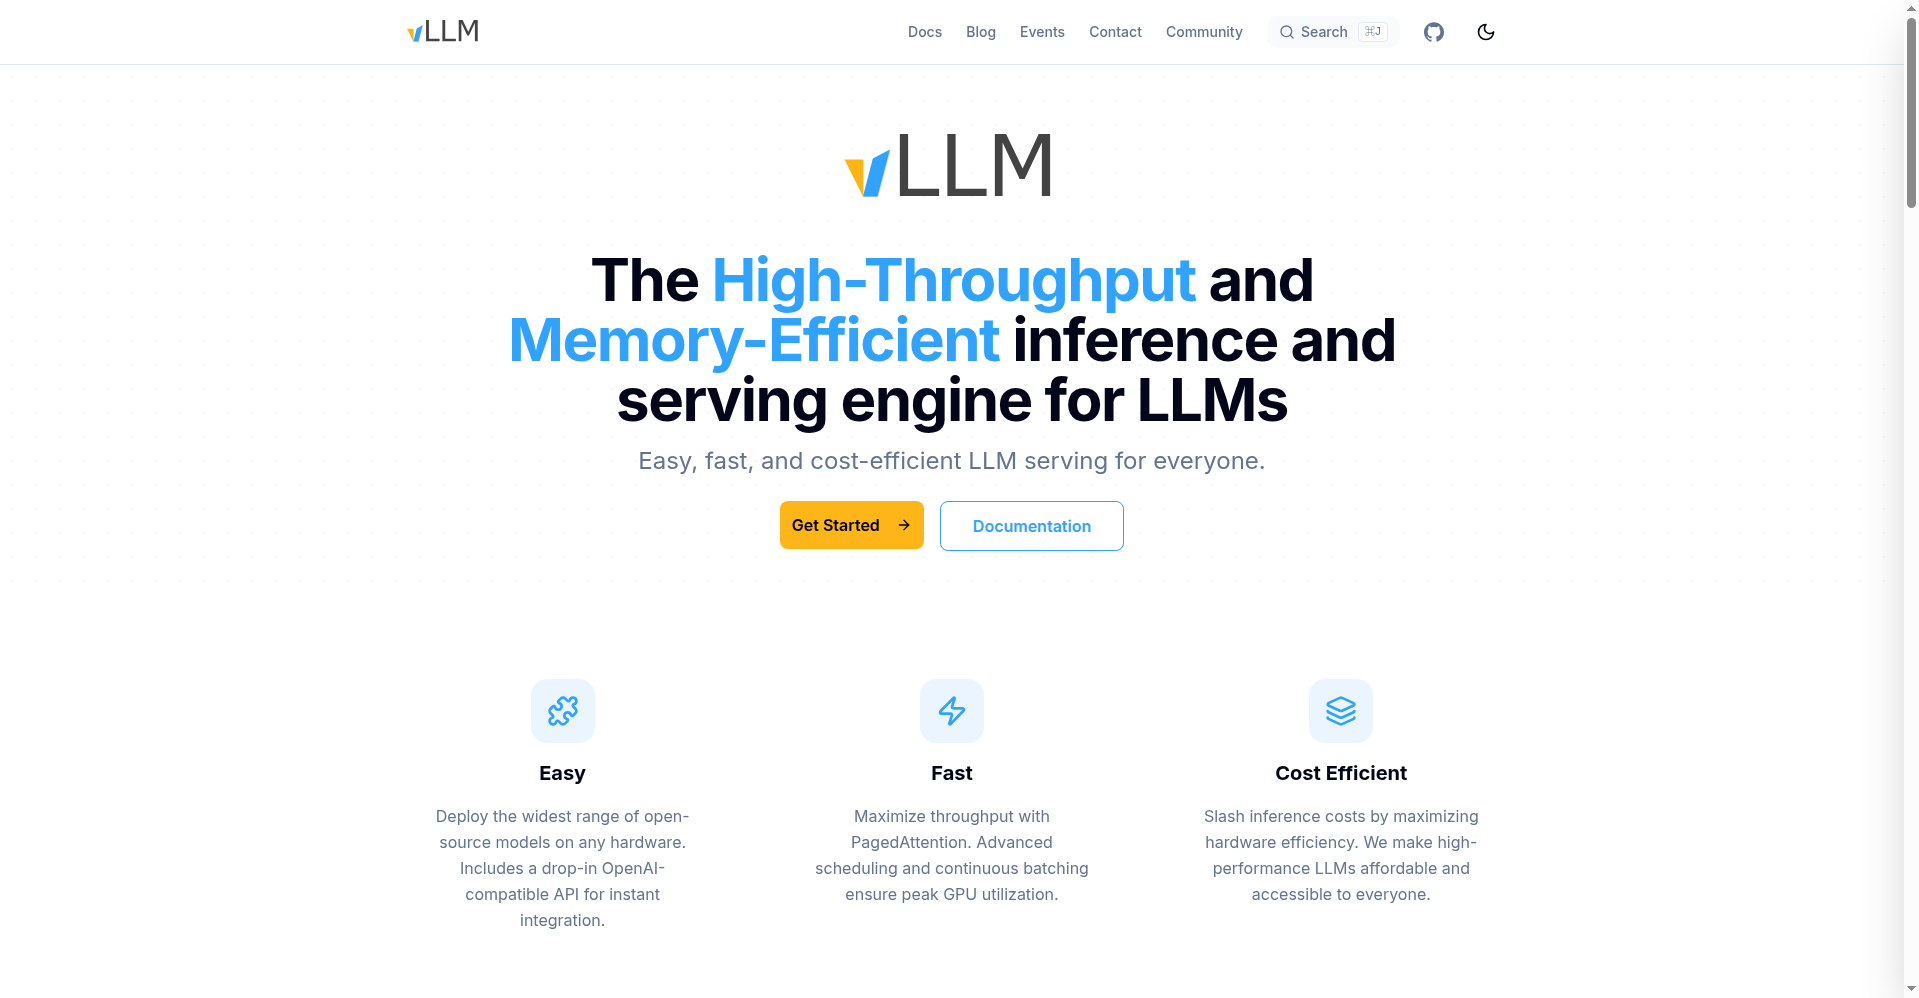
vLLM homepage — high-throughput LLM serving
Overview
What is vLLM?
High-throughput, memory-efficient inference and serving for large language models.
vLLM is an open-source library for high-throughput, memory-efficient inference and serving of large language models, originally developed in UC Berkeley's Sky Computing Lab and now maintained by a 2,000+ contributor community.
It runs open-weight models on your own GPU infrastructure through an OpenAI-compatible API server, a Python library, or offline batch inference. Key techniques include PagedAttention for KV-cache memory efficiency, continuous batching, chunked prefill, and prefix caching — plus quantization (FP8, GPTQ/AWQ, GGUF) and distributed inference. Apache 2.0 licensed; no hosted SaaS or paid tier.
Platforms and languages
vLLM Availability
Platforms
Languages
Capabilities
vLLM Key Features
PagedAttention
Memory-efficient attention KV-cache management that reduces fragmentation during generation.
Continuous batching
Batch incoming requests continuously, with chunked prefill and prefix caching for high throughput.
OpenAI-compatible server
Drop-in API server plus Anthropic Messages API and gRPC support.
Quantization support
FP8, MXFP8/MXFP4, NVFP4, INT8/INT4, GPTQ/AWQ, GGUF, and more.
Broad hardware support
NVIDIA and AMD GPUs, CPUs, and plugins for TPUs, Intel Gaudi, Huawei Ascend, and Apple Silicon.
Best for
Who uses vLLM?
ML engineers and teams
Serve open-weight LLMs at high throughput on own GPU infrastructure
Plans and access
vLLM Pricing
Free
Common questions
vLLM FAQs
What is vLLM?
A fast, open-source library for LLM inference and serving, originating at UC Berkeley's Sky Computing Lab.
Is vLLM free?
Yes — Apache 2.0 licensed, fully free and open source, with no paid tiers.
What do I need to run vLLM?
Linux, Python 3.9–3.12, and a GPU with compute capability 7.0+; CPU-only builds are also available.
Which models does vLLM support?
200+ model architectures on Hugging Face, including Llama, Qwen, Gemma, MoE models like Mixtral and DeepSeek-V3, and multimodal models.
Reviews
See what the community thinks and share your experience.
—
Based on 0 ratings
Rating distribution
Community reviews
No reviews
No written reviews yet.