Google's mid-tier Gemini 4 model for complex coding, knowledge work, and science, with a 1M-token context window.
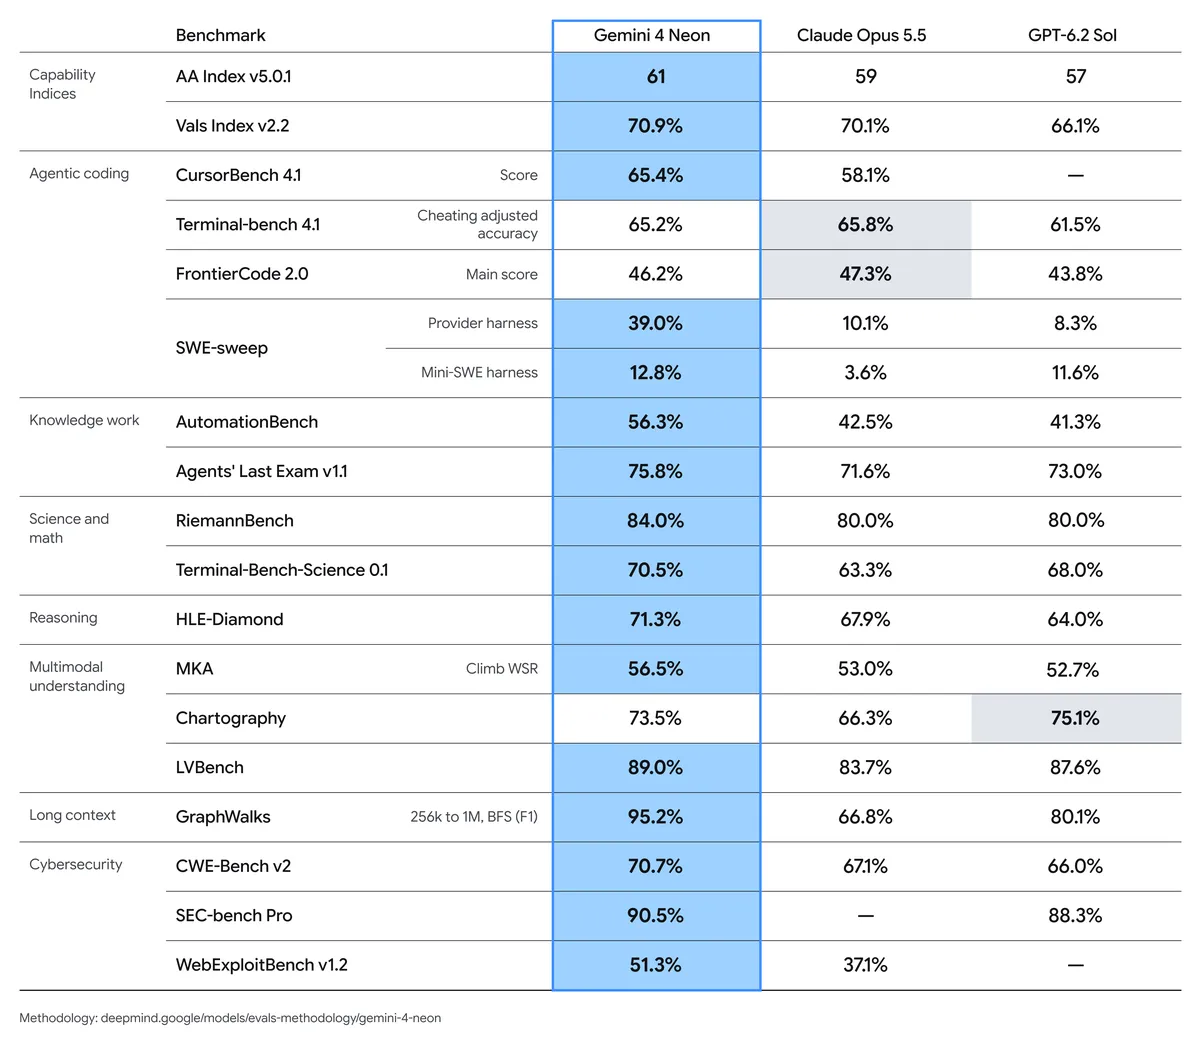
Google benchmark table: Gemini 4 Neon vs Claude Opus 5.5 and GPT-6.2 Sol
1 / 2Overview
What is Gemini 4 Neon?
Frontier-level intelligence with fast end-to-end task completion.
Gemini 4 Neon is Google's mid-tier model in the Gemini 4 family, announced on November 18, 2026. It sits between Hydrogen, the fast everyday model, and Carbon, the heavyweight for the hardest long-horizon work, and it is built for complex software engineering, knowledge work, and science workflows that run at high frequency. Neon is adapted from Carbon, according to Google's model card.
Neon costs $3.00 per million input tokens and $15.00 per million output tokens on the Gemini API Standard tier, with cached input at $0.15. Batch and Flex tiers halve the rates to $1.50 and $7.50. There is no free tier. It offers a 1 million-token unified context window and four thinking levels (low, medium, high, xhigh), with high as the default; thinking cannot be switched off.
At its xhigh thinking level Neon scores 61 on the Artificial Analysis Intelligence Index, ranking third overall, and it ranks first on the Artificial Analysis Coding Agent Index at 58.6. It is available in the Gemini API in Google AI Studio, in Gemini for business, in Google Antigravity for paid Pro and Ultra subscribers, and in the Gemini app for Pro and Ultra subscribers.
Platforms and languages
Gemini 4 Neon Availability
Platforms
Languages
Capabilities
Gemini 4 Neon Key Features
Top-ranked coding agent
Ranks #1 on the Artificial Analysis Coding Agent Index at 58.6, with 65.2% on Terminal-Bench 4.1.
1M-token context window
A unified 1,048,576-token window covering input, thinking, and output for long documents and repos.
Four thinking levels
Low, medium, high, and xhigh thinking levels, with high as the default for balanced cost and quality.
Orchestrator in Antigravity
Acts as a fast, high-judgment Orchestrator directing parallel Hydrogen subagents in Google Antigravity.
Strong enterprise results
Ranks #2 on the Vals Index at 70.9% and first on the Legal Research Bench and Tax Agent Bench.
More secure code
Produces more secure code than Carbon on AutoBaxBench, reaching state-of-the-art on the hard tier at 76%.
Best for
Who uses Gemini 4 Neon?
Developers and teams running coding agents and document workflows
Complex software engineering, knowledge work, and science tasks at high frequency
Plans and access
Gemini 4 Neon Pricing
Paid
Standard $3.00 input / $15.00 output per 1M tokens; Batch and Flex $1.50/$7.50.
Common questions
Gemini 4 Neon FAQs
What is Gemini 4 Neon?
Google's mid-tier Gemini 4 model for complex coding, knowledge work, and science workflows, launched on November 18, 2026. It sits between the fast Hydrogen and the heavyweight Carbon.
How much does Gemini 4 Neon cost?
On the Gemini API Standard tier, $3.00 per million input tokens and $15.00 per million output tokens, with cached input at $0.15. Batch and Flex tiers cost $1.50 and $7.50. There is no free tier.
How is Neon different from Hydrogen and Carbon?
Hydrogen is the fastest, cheapest model for everyday execution; Carbon is built for the hardest long-horizon work. Neon balances depth and speed for complex work that runs often.
Where can I use Gemini 4 Neon?
In the Gemini API in Google AI Studio, in Gemini for business, in Google Antigravity, and in the Gemini app — the app and Antigravity require a paid Google AI Pro or Ultra subscription.
What changes on December 1, 2026?
Carbon's introductory $2/$10 pricing ends and its rates double to $4/$20. Neon's flat $3/$15 then makes it 25% cheaper per token than Carbon.
Reviews
See what the community thinks and share your experience.
—
Based on 0 ratings
Rating distribution
Community reviews
No reviews
No written reviews yet.