Serverless LLM inference platform that issues an independent, verifiable receipt for every model API call and refunds credits on eligible failed calls.
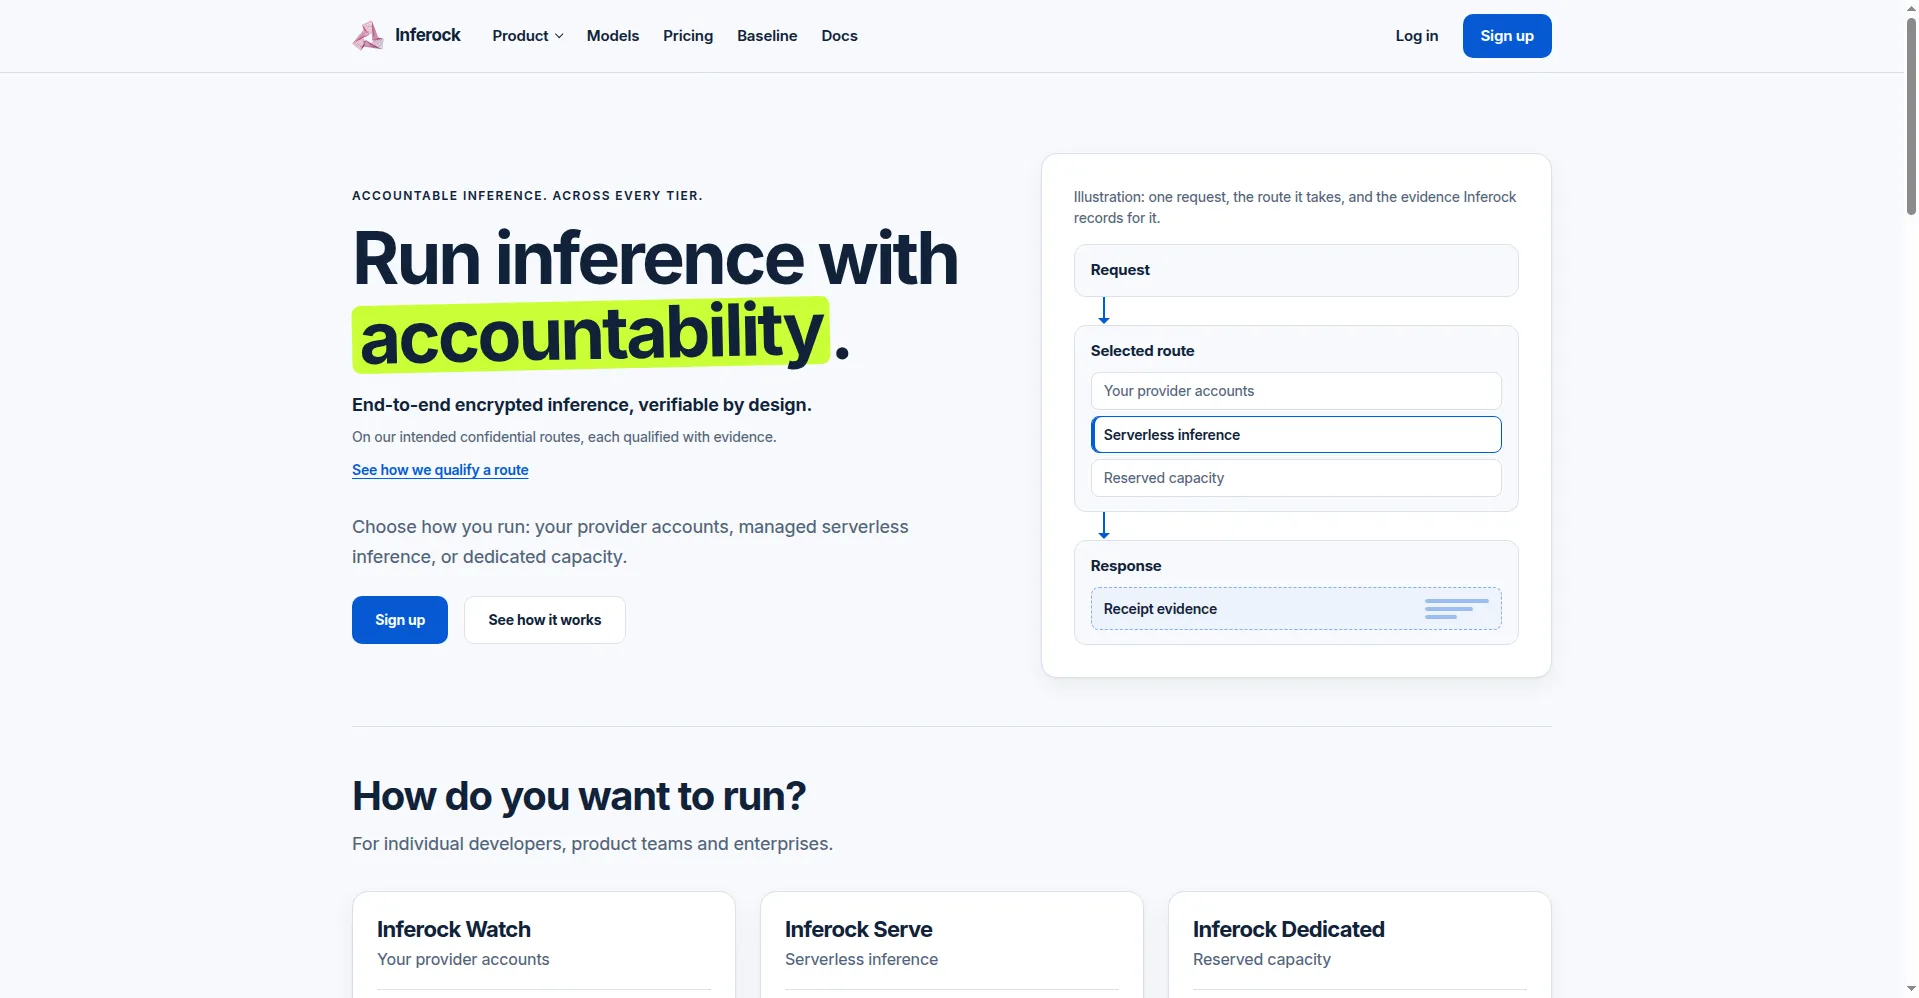
Homepage hero — accountable inference
1 / 3Overview
What is Inferock?
An independent receipt for every LLM API call
Inferock is a serverless LLM inference platform built around accountability: every model API call generates an independent receipt, measured against a public baseline for quality, speed and cost. It works in two modes. In Watch mode, teams connect their own OpenAI, Anthropic or Gemini API keys for free observability — including quality, latency and cost visibility plus a monthly inference performance report. In Serve mode, Inferock routes inference serverlessly with automatic provider selection and pay-per-token pricing, with a 10% service fee on actual supplier cost. Its failure detection catches structural failures like empty or truncated outputs and invalid structured responses, tracks quality drift with active probes, and re-routes traffic or compensates with service credits when objective failures occur. Built for teams running LLMs in production who need verifiable, end-to-end encrypted inference on confidential routes.
Platforms and languages
Inferock Availability
Platforms
Languages
Capabilities
Inferock Key Features
Per-call inference receipts
Every LLM API call is measured against a public baseline and recorded as an independent receipt covering request, routing, schema, latency, usage and response evidence.
Failure detection
Passive in-path checks catch structural failures such as empty or truncated outputs and invalid structured responses, while active probes track quality drift.
Remedy routing and credits
When an objective failure is detected, traffic is re-routed to a backup route or compensated with Inferock Serve service credits.
Watch mode with your own keys
Connect your OpenAI, Anthropic or Gemini API keys for free observability plus a monthly inference performance report.
Serverless pay-per-token inference
Run inference through Inferock Serve with automatic provider selection and pay per token, with input, cached-input and output rates shown by model.
Best for
Who uses Inferock?
LLM engineering and product teams
monitor and verify production LLM calls with per-call receipts, failure detection and cost visibility
Plans and access
Inferock Pricing
Freemium
Watch is free on your own provider keys; Serve is pay-per-token + 10% service fee; Dedicated is by agreement.
Common questions
Inferock FAQs
Is Inferock free to use?
Yes — Inferock Watch is free when you bring your own OpenAI, Anthropic or Gemini API keys. You only pay when you run inference through the paid Serve or Dedicated plans.
How does Serve pricing work?
Serve is billed pay-per-token: model rates include provider usage plus a 10% service fee on actual supplier cost. You prepay through Inferock, so no provider API key is required. Dedicated capacity is quoted by agreement.
What happens when an LLM call fails?
Inferock detects structural failures such as empty or truncated outputs and invalid structured responses. For eligible failures it re-routes the call or compensates you with non-cash service credits.
Do I need my own API keys?
Only for Watch mode, where you connect your own provider keys. Serve mode needs no provider keys — you pay Inferock directly and it selects the provider for each call.
Reviews
See what the community thinks and share your experience.
—
Based on 0 ratings
Rating distribution
Community reviews
No reviews
No written reviews yet.