A self-hosted AI observability gateway that catches model drift, traces agent runs, and tests prompts before release.
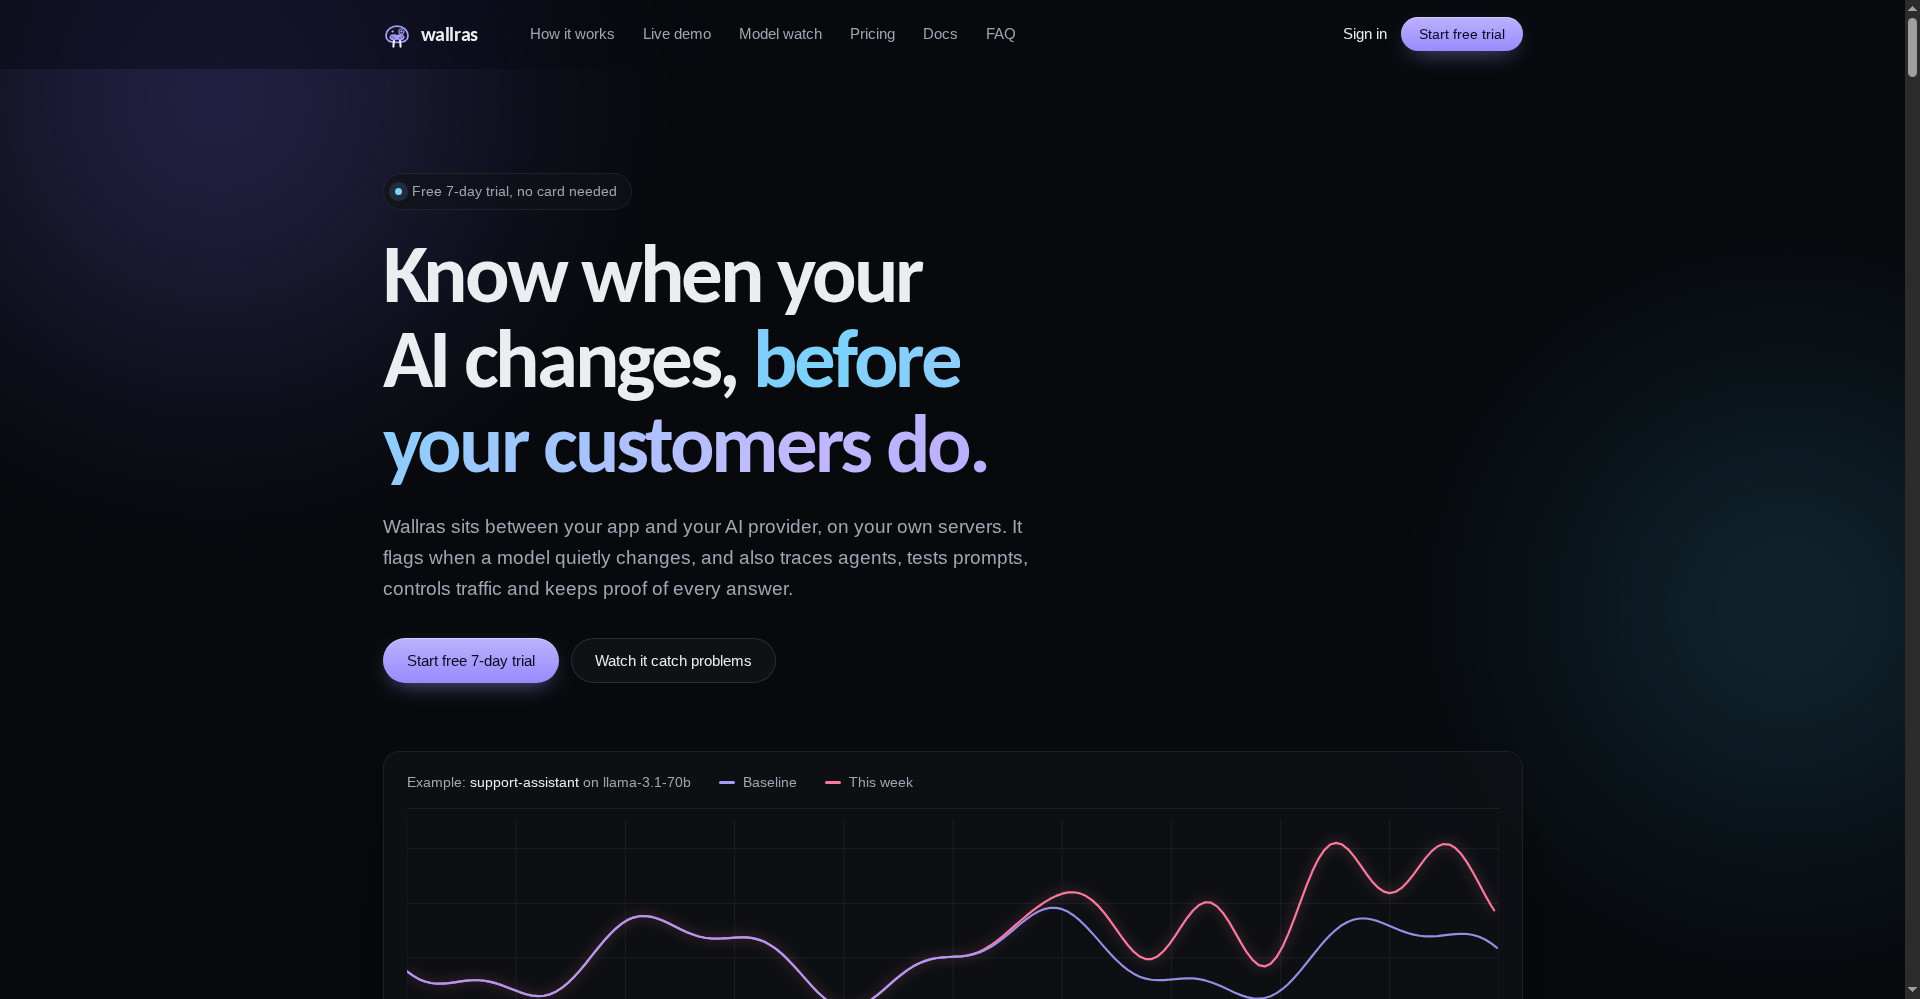
Wallras homepage
1 / 2Overview
What is Wallras?
Catch AI regressions before your customers do.
Wallras is one self-hosted container between your app and your AI provider. It catches drift and silent model swaps, traces agent runs, tests prompts before release, flags shaky answers, and keeps a tamper-evident log, while your data never leaves your servers. Prompt changes are scored with 45 checks and blocked below your threshold. Agent runs record tool calls, latency, and cost so you can find the failing step. It works with Anthropic, Gemini, any OpenAI-compatible API, and local models such as Ollama and vLLM. The Hobby plan is free for 15,000 requests a month; Builder is $39, Team $199, Scale $699, and Enterprise starts at $1,999 a month, with a 7-day free trial and no credit card required.
Platforms and languages
Wallras Availability
Platforms
Languages
Capabilities
Wallras Key Features
Drift and silent swap detection
Proxies requests through a self-hosted container and catches response changes and unannounced model swaps.
45-check prompt testing
Scores prompt changes before release and blocks them below your threshold.
Agent run tracing
Records tool calls, latency, and cost to find the failing step in an agent run.
Answer quality flags
Flags uncertain, possibly hallucinated, or off-brand answers, with optional gateway blocking.
Tamper-evident audit log
Logs every AI request and response for export and accountability, stored on your servers.
Best for
Who uses Wallras?
Teams shipping AI features who need to trust their models
Catch model drift, bad prompts, and failing agent runs before customers notice
Plans and access
Wallras Pricing
Freemium
Free Hobby plan (15,000 requests/month); paid plans from $39/month. 7-day free trial.
Common questions
Wallras FAQs
Does Wallras slow down my AI?
Barely. It adds about 5-7 milliseconds per request, and answers still go through if storage fails.
Can Wallras see my data?
No. It runs self-hosted on your servers; paid plans only send a license key, install ID, and request counts.
Which providers does it support?
Anthropic, Gemini, any OpenAI-compatible API, and local models such as Ollama and vLLM.
Will it increase my AI bill?
No. It does not make calls on its own by default, and extra checks are off unless you enable them.
Does it change my AI answers?
No. By default it only observes; it blocks answers only if you turn on gateway features.
Reviews
See what the community thinks and share your experience.
—
Based on 0 ratings
Rating distribution
Community reviews
No reviews
No written reviews yet.