
Gemini 4 Hydrogen Explained: Google's Fast Model for Agentic Work
Google's Gemini 4 family had a gap. Carbon and Argon were built for deep, long-horizon reasoning, the kind of work where a model spends a long time thinking before it answers. But most everyday work is not like that. Most of the time you want a model that moves fast, follows instructions, calls the right tools, and gets out of the way. On November 12, 2026, Google DeepMind filled that gap with Gemini 4 Hydrogen, the fast execution layer of the Gemini 4 family.
Hydrogen is not another frontier model. It is the model Google wants running underneath your daily work: repository coding, debugging, document synthesis, and multi-step agent workflows. It is also, from launch day, the default model behind Search AI Mode for all users.
Hydrogen's job inside the Gemini 4 family
Google's framing is simple. Carbon and Argon handle the hard thinking. Hydrogen handles the doing. In the launch post, Koray Kavukcuoglu, SVP of Google DeepMind and Google's Chief AI Architect, positions Hydrogen as a model built for "rapid execution across diverse agentic workflows," either on its own or paired with Carbon and Argon as the execution engine in multi-model work.
Google also introduced Orchestrator in Google Antigravity, which switches between models inside one session: Carbon plans, Hydrogen executes. Google reports near-Carbon success on Terminal-Bench 4.0 with 24 percent less quota and 19 percent faster completion.
The model ID is gemini-4-hydrogen; according to the model card, it is adapted from Carbon, with a knowledge cutoff of March 2026.
The headline numbers, and whose numbers they are
Every performance figure in this section comes from Google's launch materials. Treat them as the company's claims about its own model, not as independent findings.
The headline score is on the Artificial Analysis Intelligence Index, a composite of knowledge, reasoning, coding, and professional tasks. Google says Hydrogen scores 51 at its default high thinking level, against 50 for Argon, and reaches 54 at its new xhigh level. Artificial Analysis's own pages list the same figures, along with 31 for Gemini 3.8 Flash at high, which puts the scale of the jump in context.
On speed, Google says Hydrogen finishes tasks 2.5 times faster than 3.8 Flash at its default setting, and more than triples Terminal-Bench 4.1 scores, from 18.2 percent to 57.0 percent, while cutting fabricated claims by more than five times. On agentic benchmarks it reports a fifth-place ranking on Agent Arena, a class-leading 58.8 percent on HLE-Diamond, first place overall on the Vals Tax Agent Bench at 52.3 percent, and 71.6 percent on Agents' Last Exam v1.1.
Two numbers deserve a second look. First, the 2.5x speed claim was measured on agentic work with tool calls, not on short single-turn prompts. An independent test by RanThis, run on November 13 on three short office tasks, found Hydrogen about 1.5 times faster than 3.8 Flash at its default level. The direction of Google's claim held up; the size did not, at least on short tasks. Second, the one-point lead over Argon is narrow, and it comes at the default thinking level, where Hydrogen spends more tokens reasoning than Argon does. That trade-off shows up on the bill.
Four thinking levels, one flat price
Hydrogen ships with four thinking levels: low, medium, high, and a new xhigh tier. The default is high, a change from 3.8 Flash, Carbon, and Argon, which all default to medium.
Artificial Analysis scores each level separately, and the spread is wide: 27 at low, 41 at medium, 51 at high, and 54 at xhigh. Dropping from high to low costs roughly half the index score, while climbing to xhigh buys three points at a much higher token cost. For everyday coding and agent work, high is the sensible default. Low is for fast, cheap, routine calls. Xhigh is for the occasional problem worth paying several times more to solve.
Pricing is flat across the entire 1 million-token context window: $1.50 per million input tokens and $7.50 per million output tokens, with thinking tokens billed as output. There is no long-context surcharge. Cached input costs $0.075 per million tokens, a 95 percent discount, but caching is implicit only, for prompts of at least 4,096 tokens. Batch and Flex modes halve both prices to $0.75 and $3.75. Synchronous output caps at 65,536 tokens per call. Hydrogen is also the first Gemini 4 model with a free tier: Google lists it as free of charge on the API free tier, rate-limited, while Argon and Carbon are paid only.
Flat per token is not flat per task
Here is the part of the story that the price list does not tell you. Hydrogen is the cheapest Gemini 4 model per token, but it is not automatically the cheapest per task. The reason is the thinking level. Hydrogen thinks on every call, even at low, and thinking tokens are billed as output at $7.50 per million.
RanThis measured this directly on November 13, running three office tasks and ten hard maths problems through the API. On the office set, Hydrogen at its default high level cost $0.0723, against $0.0195 for Argon and $0.0387 for 3.8 Flash. The model with the lowest per-token price cost 3.7 times as much as Argon and nearly twice as much as Flash on the same work, because it spent far more tokens thinking. At low, Hydrogen still cost $0.0506, 2.6 times Argon's bill. Xhigh bought nothing on these tasks, costing $0.1855 on office work and $0.4995 on maths for the same perfect scores.
That is one kind of task, though. Artificial Analysis's longer benchmark tasks tell a different story: its weighted average cost per Intelligence Index task is $1.87 for Hydrogen at high, against $7.77 for 3.8 Flash and $4.97 for Argon. On long, tool-using work, Hydrogen's speed and efficiency win. On short, high-volume calls, its thinking tokens dominate the bill. Both measurements are real; they describe different workloads. The practical rule is to match the model to the job: long agentic runs favor Hydrogen, short repetitive calls favor Argon or Carbon at low. The gap will narrow soon: Argon and Carbon double from $2 and $10 to $4 and $20 on December 1, and Flash rises from $0.75 and $3.75 to Hydrogen's $1.50 and $7.50 on January 1, 2027, while Hydrogen's flat rate has no such step.
Five places you can use Hydrogen today
Hydrogen rolled out globally on launch day. Here are five places to try it.
Google Gemini. The Gemini app is the simplest way to meet Hydrogen. It is available in the model dropdown, and it is the model now answering in Search AI Mode for all users, with no opt-in needed.
Google AI Studio. AI Studio is where developers try Hydrogen first. It is available across all tiers, including the free tier, and it is the fastest way to test the four thinking levels on your own prompts. Set the thinking level, watch the token counts, and compare the bill at low against high before wiring the model into anything that runs at volume.
GitHub Copilot. On November 13, GitHub announced that Hydrogen is generally available in GitHub Copilot, one day after Google's launch. It is available to Copilot Pro, Pro+, Max, Business, and Enterprise users, selectable from the model picker in VS Code, Visual Studio, JetBrains IDEs, Xcode, Eclipse, the Copilot CLI, the coding agent, the Copilot app, github.com, GitHub Mobile, and the Copilot SDK. Rollout is gradual, so it may not appear for everyone at once. Billing is usage-based at Google's list price. GitHub will deprecate Gemini 3.8 Flash across Copilot on December 14, 2026, and names Hydrogen as the suggested replacement, which makes switching now a matter of timing rather than choice.
Google Antigravity. Antigravity is Google's agentic development platform, and it is where Hydrogen's multi-model role is most visible. Paid Google AI Pro and Ultra subscribers can use Hydrogen there, and the new Orchestrator feature pairs it with Carbon in the same session: Carbon plans, Hydrogen executes and verifies.
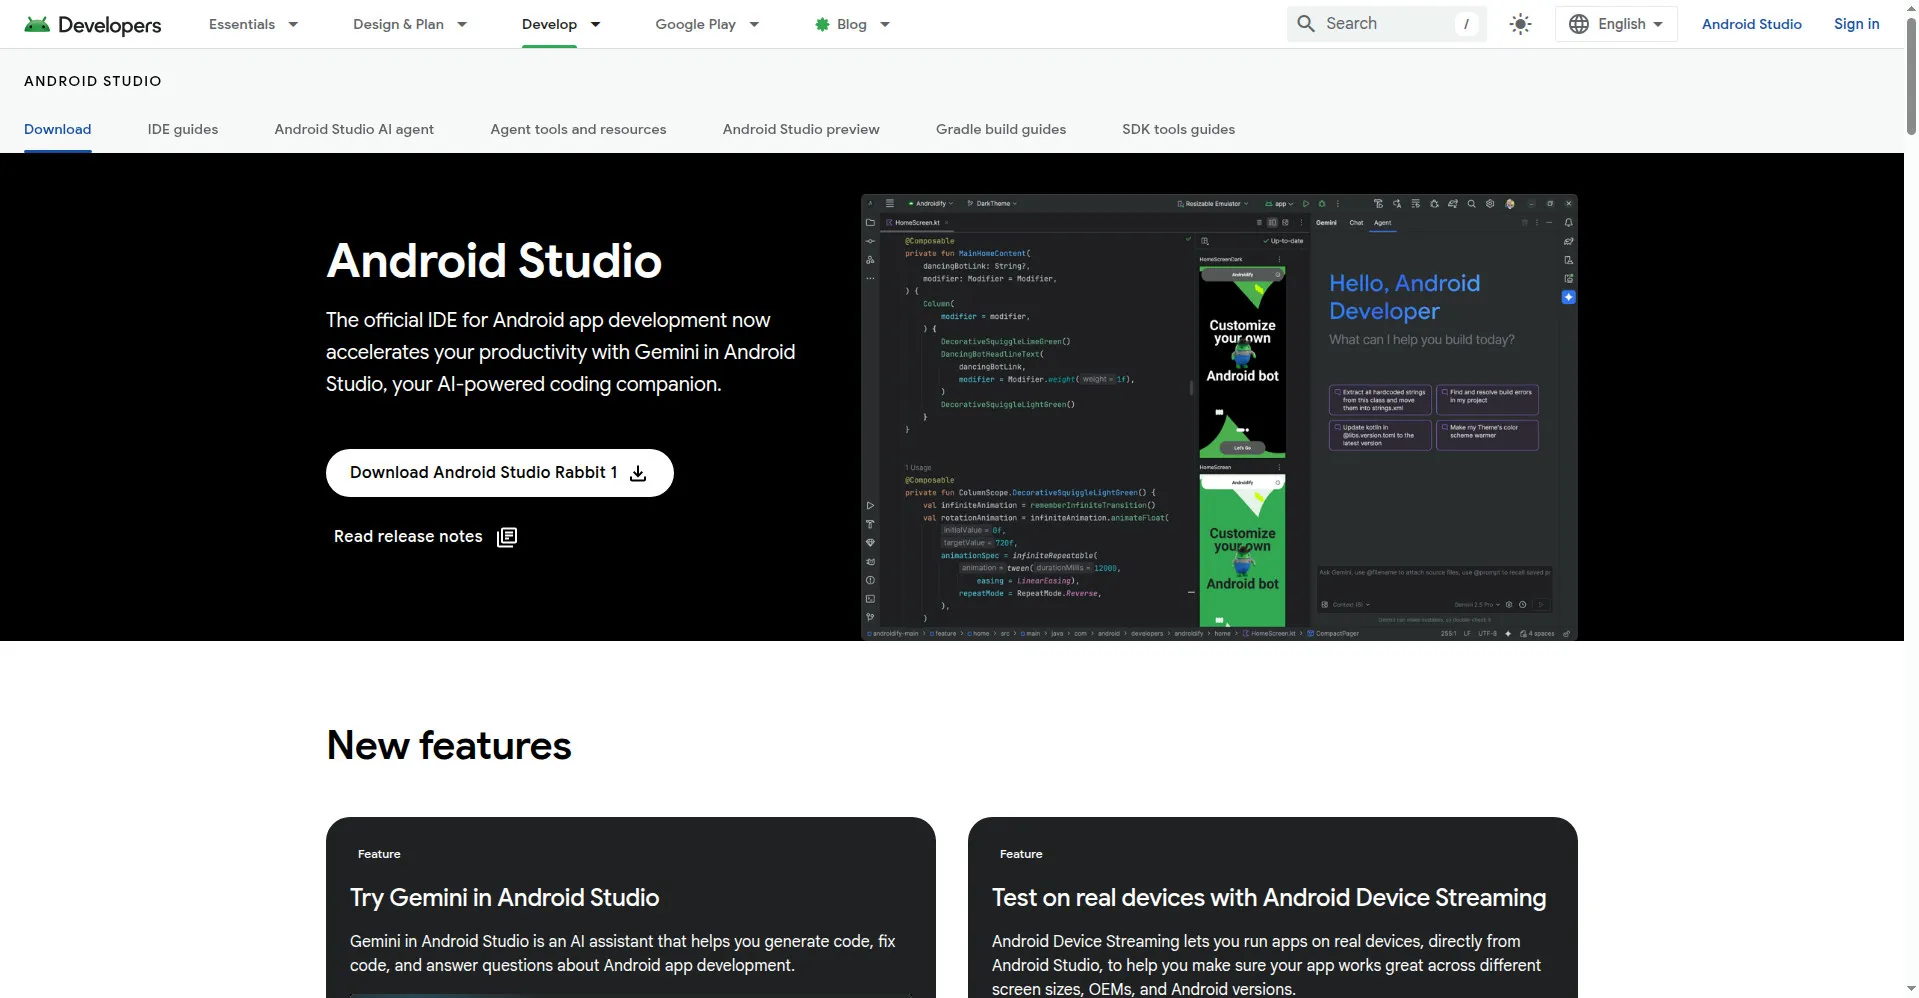
Android Studio. Android Studio is the official IDE for Android development, and Gemini in Android Studio is its AI-powered coding companion. Hydrogen is available there for repository coding, debugging, and answering questions about a codebase.
Who should switch now, and who should wait
For most people, Hydrogen is a switch to make, not a decision to agonize over. If you use Search, you are already on it. If you use Copilot, GitHub is retiring 3.8 Flash on December 14, so move before then. If you build with the Gemini API, Hydrogen's flat pricing and free tier make it the default starting point for new agent work.
Two groups should be more deliberate. If you run short, high-volume API calls, test the bill before migrating from Argon or Flash: Hydrogen's thinking tokens can make a cheap-looking model the expensive one. And if you do the hardest reasoning work, keep Carbon or Argon for that; a single index point is not a reason to downgrade your planning model.
The honest summary is this. Hydrogen is Google's fast, cheap-per-token workhorse, and it is genuinely good at the agentic coding and everyday work it was built for. Its price is predictable, its speed is real, and it is already everywhere Google's products are. But its bill depends on how much it thinks, and the default setting thinks a lot. Start at low, measure, and let the task decide the level.
Sources
- Google DeepMind Blog — blog․google
- GitHub Changelog — github․blog
- Artificial Analysis — artificialanalysis․ai
- RanThis — ranthis․com
- LiteLLM Documentation — docs․litellm․ai