Runcrate
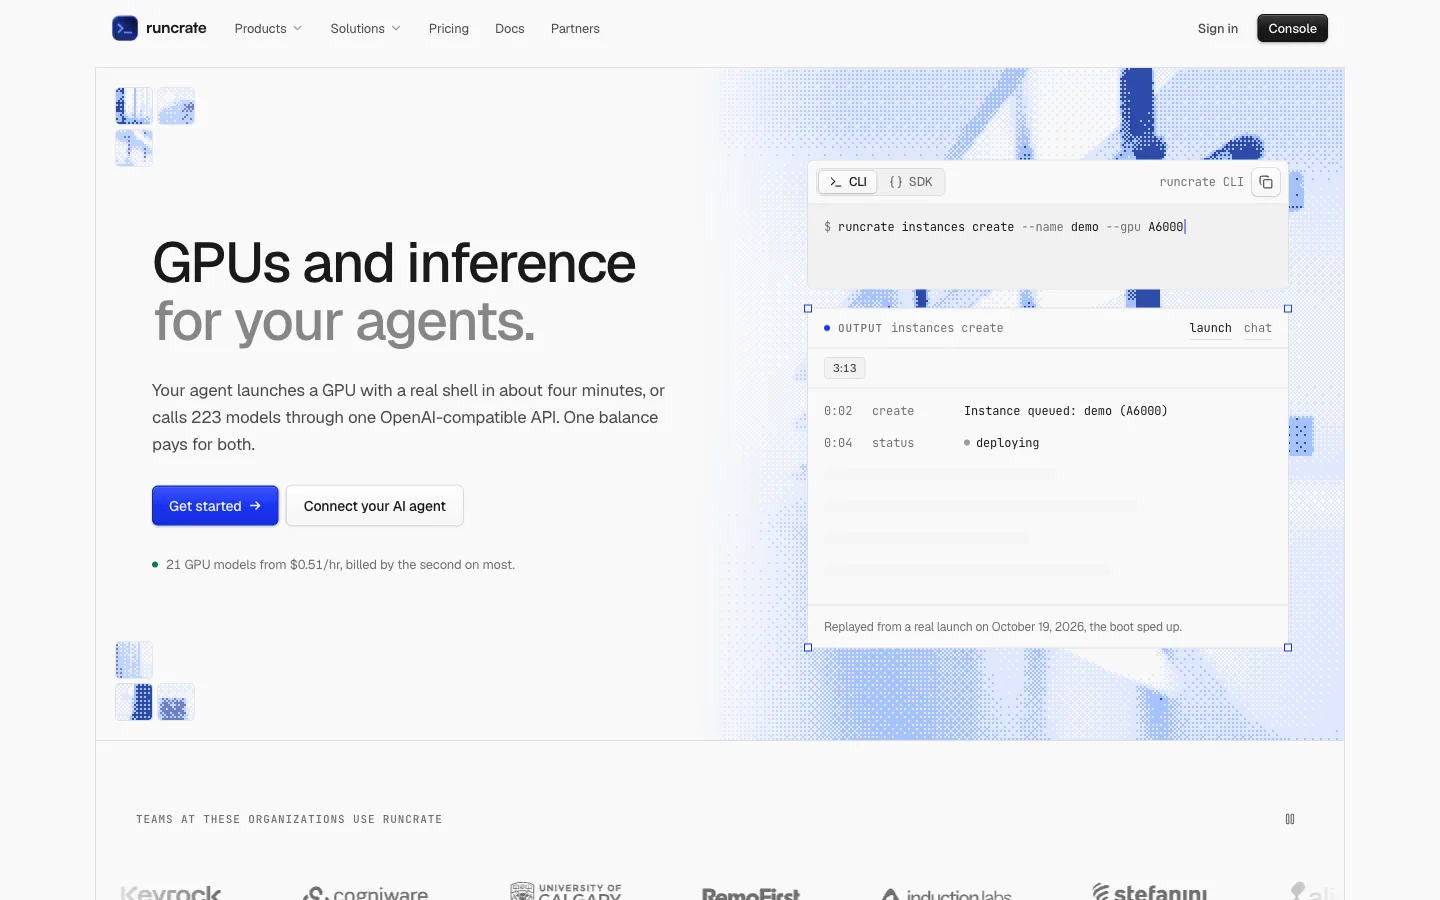
GPUs and inference for your agents: on-demand GPUs and 200+ open models behind one OpenAI-compatible API.
On-demand GPUs and 200+ open models behind one API, launchable by your AI agent.
light-viewport.png
1 / 2Overview
What is Runcrate?
GPUs and inference for your agents: on-demand GPUs and 200+ open models behind one OpenAI-compatible API.
Runcrate gives AI teams and their agents GPUs and inference from one account.
Instances
Rent a GPU by the hour (H100, H200, A100, L40S, RTX 4090, RTX PRO 6000 and more, 20+ models) with SSH, Jupyter and VS Code in the browser. A launch reaches running in about four minutes, booting is never billed, and most GPUs bill by the second.
Inference
200+ open models (DeepSeek, Qwen, Llama, Kimi, FLUX, Whisper) behind one OpenAI-compatible API, so the client you already use works. Priced per token, image or second.
Storage and clusters
Storage volumes keep datasets and checkpoints between instances, and reserved clusters cover 8+ GPUs or month-long terms.
Built for agents
Connect Claude Code, Codex or Cursor to the Runcrate MCP server with one command and sign in through your browser, no key to paste. Your agent can then launch a GPU, run commands on it and shut it down. Also a CLI (brew install aeonmindai/tap/runcrate) and Python and TypeScript SDKs.
Platforms and languages
Runcrate Availability
Platforms
Languages
Capabilities
Runcrate Key Features
GPU instances by the hour
20+ GPU models (H100, H200, A100, L40S, RTX 4090 and more) with SSH, Jupyter and VS Code in the browser. About four minutes to running; booting is never billed and most GPUs bill by the second.
200+ open models, one API
Call DeepSeek, Qwen, Llama, Kimi, FLUX, Whisper and more through one OpenAI-compatible API, priced per token, image or second.
MCP server for AI agents
Connect Claude Code, Codex or Cursor to https://mcp.runcrate.ai/mcp and sign in through your browser, no API key to paste. Your agent can launch a GPU, run commands on it and shut it down.
CLI and SDKs
brew install aeonmindai/tap/runcrate, Python and TypeScript SDKs, and a Vercel AI SDK provider.
Storage volumes and reserved clusters
Persistent volumes keep datasets and checkpoints between instances; reserved clusters cover 8+ GPUs or month-long terms by quote.
Best for
Who uses Runcrate?
AI developers and ML engineers
Fine-tune an open model with LoRA, serve a model with vLLM, or run ComfyUI/FLUX on an RTX 4090 without a long-term contract.
Teams building AI agents
Give Claude Code, Codex or Cursor a GPU on demand through the MCP server, or call 200+ models through one OpenAI-compatible API.
Plans and access
Runcrate Pricing
Paid
Usage-based, pay as you go from one prepaid balance. No subscription and no monthly fee. GPU instances are billed per hour (most GPUs by the second, booting never billed); inference is priced per token, image or second. Live prices on the pricing page.
Common questions
Runcrate FAQs
Runcrate Alternatives
 AI Sandboxes by BuddyOn-demand isolated Linux cloud machines giving AI coding agents their own persistent, secure workspace with root access.
 Liquid InferenceAn LLM router where providers bid for every prompt, giving you the lowest price that meets your requirements.
Reviews
See what the community thinks and share your experience.
—
Based on 0 ratings
Rating distribution
Community reviews
No reviews
No written reviews yet.